

An AI curated single-cell data RNA-seq repository
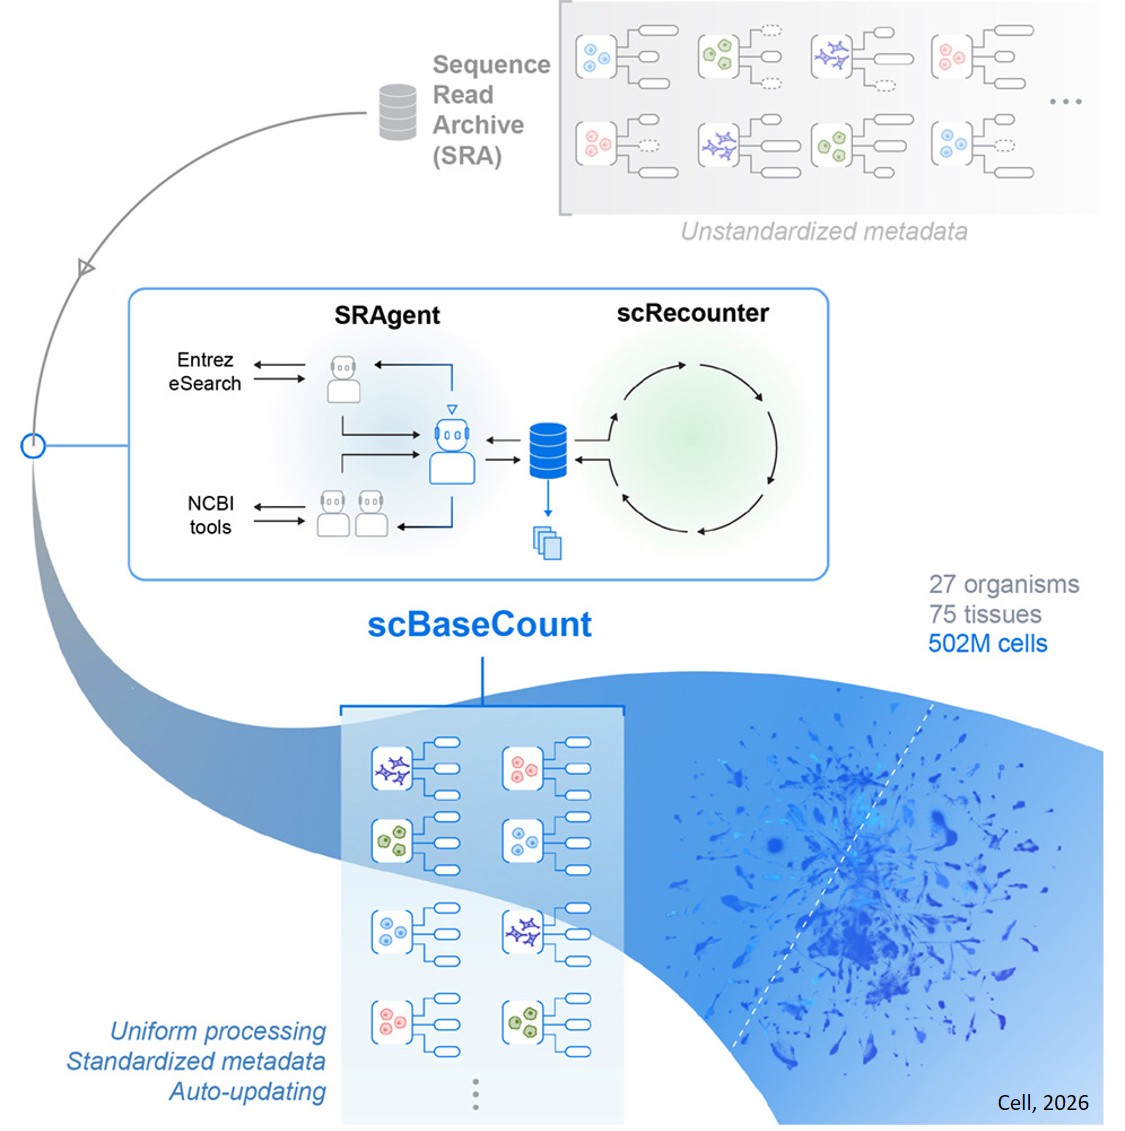
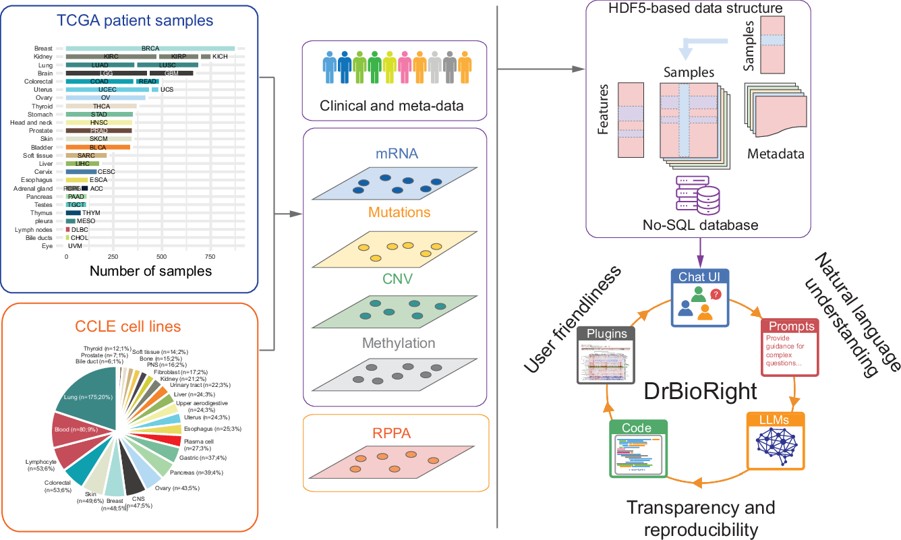
scBaseCount is presently the largest public single-cell RNA-seq repository, containing over 502 million cells across 27 organisms and 75 tissues.
The study solves a major bottleneck in genomics, the underutilization of the Sequence Read Archive (SRA) due to chaotic, unstandardized user metadata and massive raw data processing costs. By pairing a hierarchical AI agent with automated high-throughput pipelines, scBaseCount offers a blueprint for autonomous, self-updating data curation across the life sciences.
An AI agent autonomously discovers, annotates, and uniformly reprocesses all 10× Genomics datasets in the SRA, creating a harmonized, continually updated resource for studying the diversity of cell biology and training AI models.
Machine learning models are highly sensitive to batch effects from mixed software versions. Training AI cell-state foundation models on scBaseCount's unified data landscape markedly boosts their precision, allowing them to differentiate subtle, complex biological phenotypes, disease mutations, and drug perturbations.